
Advanced HTML TOC
Version 2.0
Shareware
$29.00
0 downloads
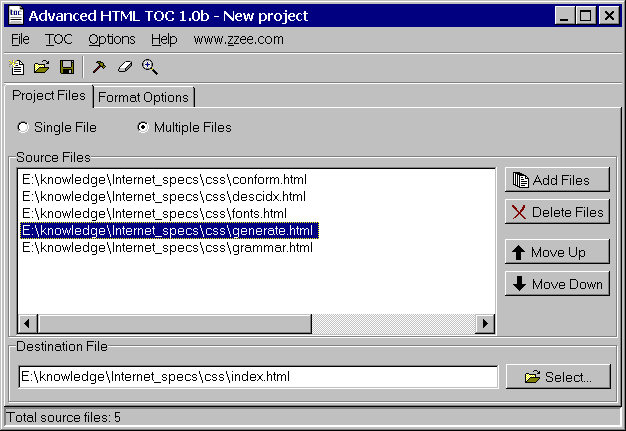
Program creates table of contents (TOC) of HTML files
from header header tags. It does:
- Can process single or multiple files.
- Automatically uses existing named anchors inside
header tags or creates new ones if none.
- Automatically links TOC items to header tags.
- User sets range of header tags being used in TOC.
This can be used to create TOCs of various depths from
the same files.
- Can process page titles, which is useful for
multiple file processing. Titles have precedence over
H1 tag.
- Completely re-entrant. If you change the file after
you have generated TOC, when you again supply it to
the program, the program doesn't create redundant
named anchors and doesn't duplicate TOC.
- Can put numbering (like "1.20.4.") both into TOC
items and header tags. If multiple files are processed
then numbering is kept in order throughout all files.
- TOC appearance is based on a template. User can
create a new template or edit existing one. Program is
shipped with some predefined templates. You have total
control over TOC style.
- User specifies a place where to insert TOC. IF place
is not specified, program selects a place
automatically.
Program details
Publisher
Paul SlavicE-mail
Contact the publisherHome page
http://www.zzee.com/aht/Platforms
Windows 95<br>Windows 98<br>Windows ME<br>Windows File size
366 KBFile date
8/18/2002License
SharewareExpiration info
no expirationInstallation
Install & UninstallRecord updated
8/19/2002


